A sentiment tag looks simple: positive, negative, neutral, or mixed. The difficult part is deciding whose attitude the label describes, what the attitude concerns, and whether the text contains enough evidence to make that judgment. In a news or research feed, a cheerful quotation can appear inside a critical article, while a negative event can be described in neutral language.
This guide proposes an evaluation process for sentiment annotations in a fictional editorial collection. The goal is better reading context, not a prediction engine or an automated judgment about people. The Sentiment Tags Feed overview introduces the scope; here we focus on task definitions, examples, error analysis, and responsible presentation.
Define the unit and the target first
Choose what receives a label: a headline, a sentence, a paragraph, or the whole article. Then identify the target of that sentiment. A review can praise a product's design while criticizing its reliability. One document-level label compresses those different attitudes into a single value. That may be acceptable for a narrow task, but it should be an explicit compromise.
Write a plain-language annotation question. For example: “What attitude does the author express toward the proposed workflow in this paragraph?” That is more precise than “Is this article positive?” It also helps reviewers distinguish the author's stance from a quoted speaker's view. Keep the same question in training examples, evaluation instructions, and the public explanation of the annotation.
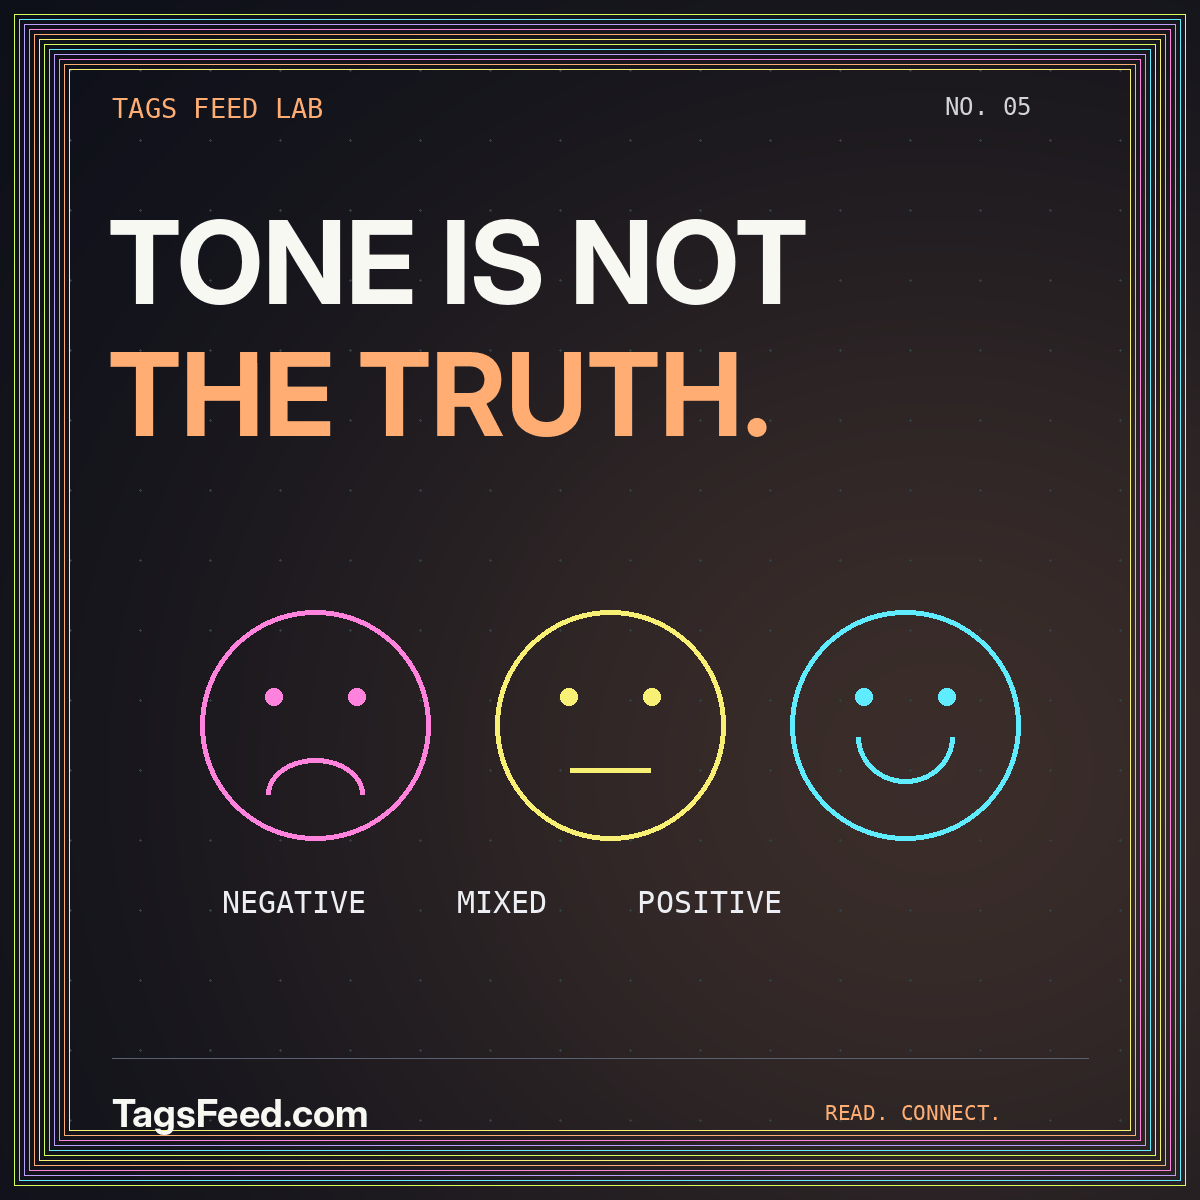
Do not confuse tone with truth or outcome
Sentiment is not a fact-check. A confident, upbeat article can contain errors; a critical article can be carefully supported. Likewise, a negative description does not establish that an organization will fail or that a market will move in a particular direction. Do not build a presentation that quietly substitutes emotional tone for evidence about the world.
Google's Natural Language sentiment documentation describes an analysis task that identifies emotional opinion and returns sentiment information for text. Its example distinguishes positive and negative score values. That is a useful illustration of the task's output, not a reason to interpret every model's scale identically or to treat an annotation as verified reality.
Create an annotation guide with hard examples
Use examples that force the boundaries into the open. “The interface is attractive, but the export repeatedly fails” contains different evaluations of different aspects. “The report describes a severe outage” may report a negative event without expressing the writer's own emotional attitude. Explain how each example should be handled under your chosen task definition.
Include an abstention rule. Some texts contain too little evidence, an unclear target, or competing viewpoints that cannot be reduced usefully. Allow reviewers to choose uncertain or mixed where appropriate. A system that always returns a confident label may look tidy while hiding ambiguity. An honest empty field can be more useful than a misleading badge.
Keep quotation boundaries visible
When a source quotes several people, preserve speaker attribution during extraction. A paragraph that loses its quotation marks or introductory sentence can appear to express the opposite editorial position. Test extraction separately from classification. Otherwise, reviewers may blame the model for an error created when the original document was converted into plain text.
Assemble a representative evaluation set
Sample the material you expect to publish, not only convenient examples from a different domain. Include short announcements, long explanations, reviews, interviews, and multilingual items where relevant. Separate topics with distinctive language. A sports recap and a software incident report may use negative words in very different ways, even when both belong to the same overall collection.
Ask more than one reviewer to label a subset independently. Discuss disagreements and revise the guide before treating those labels as reference answers. Keep disputed cases visible instead of silently selecting whichever judgment agrees with the model. The disagreement itself may show that the task needs a narrower target or an additional category.
Report mistakes by type, not just a headline score
Count false positive and false negative decisions for the labels that matter to your use case. Inspect mixed and uncertain cases separately. A model can appear successful overall while performing poorly on a small but important category. Keep an error table with the text, expected interpretation, observed label, and a brief explanation of what went wrong.
Break the results down by source type, language, and text length when your sample supports those comparisons. Avoid drawing strong conclusions from tiny groups. If the sample is too small, say so in the internal evaluation rather than presenting a precise percentage without context. The purpose of the report is to guide a decision, not to decorate a dashboard.
Treat scores as model-specific measurements
A numerical sentiment output needs a definition. Some systems expose separate quantities for direction and strength; others produce class probabilities or uncalibrated scores. Do not place different model outputs on one universal axis without a mapping you have actually tested. Preserve the original model identifier and task configuration with each experimental result.
Choose display thresholds from observed behavior on your material. A threshold is a policy decision about which errors you are willing to tolerate, not a universal constant. Review borderline examples before deciding where a badge appears. The Decision Model Tags Feed page explains how annotations can inform a review rule without becoming an automatic high-stakes decision.
Design an interface that keeps context nearby
Place the label beside a clear explanation of what was classified. “Author tone toward the workflow” is more informative than an unexplained colored dot. Give the reader a route to the relevant passage and the complete article. Avoid using only red and green to convey meaning; words should carry the interpretation even when color is unavailable.
Consider whether the label is useful at all for a given archive. A reader seeking a technical tutorial may care more about its topic and difficulty than its emotional tone. An annotation should earn its place by answering a reader question. Adding another badge simply because the pipeline can generate it increases visual complexity without necessarily improving understanding.
Monitor changes in sources and language
A classifier evaluated on one period of content may encounter different phrasing later. New product names, recurring jokes, and changes in editorial style can alter the examples it sees. Review a fresh sample periodically and compare error types with the earlier set. Do not assume an unchanged model means the surrounding task has stayed unchanged.
Preserve the source text used for each reviewed result, subject to your content-handling policy. When a source is corrected, reconsider any sentiment label derived from the older version. Store the original annotation and the revision separately in the internal history when you need an audit trail. That helps distinguish a source change from a classifier change.
Keep operational scope proportionate
Begin with an internal editorial aid rather than automatically ranking every public item by sentiment. A small review queue lets you discover whether the labels help an editor choose reading order or identify contrasting viewpoints. Measure that usefulness alongside classification errors. Accuracy on a test set does not automatically mean the interface improves the reader's task.
Avoid applying sentiment labels to infer an individual's personality, mental state, or future behavior. Keep the task tied to the text and the defined target. For collections discussing markets or public events, separate sentiment annotations from outcome data and avoid implying that one predicts the other. This boundary is especially important when a compact label could be mistaken for advice.
Conclusion: make the question as clear as the label
A responsible sentiment workflow defines its unit, target, ambiguity rules, and evaluation method before assigning colors. It treats numerical outputs as model-specific and keeps the source context within reach. Most importantly, it does not ask a tone label to answer questions about truth, importance, or future outcomes.
Continue with the AI summary review workflow to connect sentiment experiments with broader rules for evidence, review, and corrections. Both tasks benefit from the same discipline: preserve the original material and make the limits of the derived annotation understandable.